4 min read - LM Studio or Ollama: Choosing a Local Model Workflow
Local AI Deployment & Open Source
For CTOs and engineering leaders
Published August 21, 2025 · Author Exceev Consulting
LM Studio and Ollama can both run models behind a local API, but they should not be compared through a stale table of token prices, laptop prices or promised break-even dates. The useful distinction is the workflow your team needs and the controls it can operate.
What the official documentation confirms
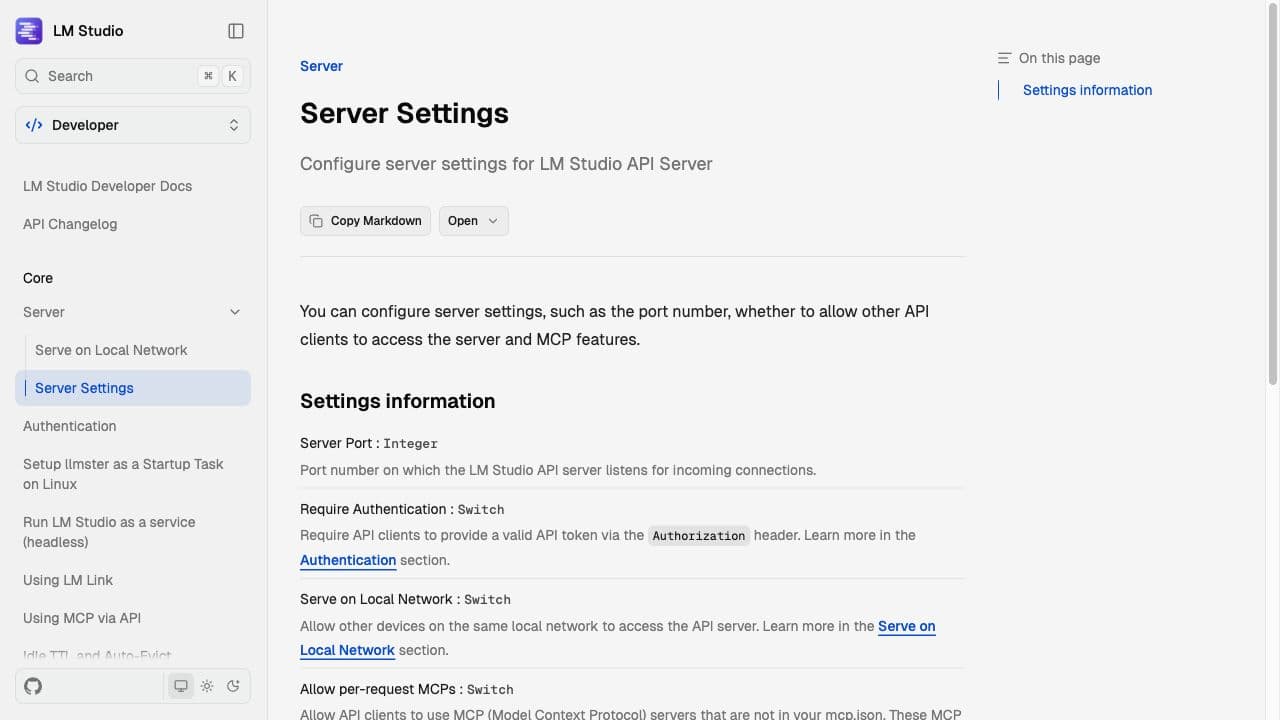
LM Studio provides a desktop workflow, command-line tooling, SDKs and local HTTP APIs. Its documentation describes native REST endpoints as well as compatibility endpoints. The local server binds to localhost by default; authentication can be enabled, and exposing it to a network requires a deliberate configuration change.
Ollama exposes a local API and official Python and JavaScript libraries. Its documentation states that the local API does not require authentication. That default is convenient for a developer workstation, but it also means a team must design its own network boundary before using the service beyond localhost.
These product facts do not establish which tool is faster, cheaper or more accurate. Model, quantisation, context, hardware, prompt and concurrency all affect those outcomes.
Choose by operating mode
LM Studio may suit a person who wants to inspect and test models through a desktop application while retaining API and CLI options. Its current developer documentation also covers a headless daemon for non-GUI use.
Ollama may suit a command-line and API-centred workflow in which model configuration and application integration are the main interface. Verify the current API and model documentation for the version you deploy.
Do not infer licence terms from the fact that a tool runs local models. Review the licence for the application, runtime and every model separately. “Open weights” also does not mean unrestricted use.
Local does not automatically mean private
Running inference on a controlled machine can reduce the need to send prompts to a third-party inference service. It does not, by itself, secure the workflow. Check:
- where model files and chat history are stored;
- whether the server listens only on localhost;
- how API clients authenticate;
- whether tools or MCP servers can reach files and remote services;
- what telemetry, update and model-download paths exist;
- who can read logs, prompts and generated output.
LM Studio's documentation explicitly warns about network binding, CORS and tool access. Ollama's documentation confirms that its local API has no authentication requirement. Treat both as design inputs.
Benchmark the exact workload
Hardware guidance ages quickly, and parameter count is not enough to predict memory or speed. Download the exact model and format you intend to use, then test on the target machine.
Record:
- model identifier, licence and file hash;
- quantisation and context length;
- prompt and output lengths;
- time to first token and sustained throughput;
- peak memory under expected concurrency;
- task quality on a reviewed evaluation set;
- failure behaviour when the context or memory limit is reached.
Quantisation reduces weight precision and can shrink a model, but the llama.cpp documentation also notes that it may reduce accuracy. Measure that trade-off on the task instead of repeating a universal quality-loss percentage.
Calculate cost from your own bill
Local inference still has costs: hardware, electricity, engineering time, monitoring, storage, upgrades and idle capacity. Cloud inference has usage charges, integration work and vendor dependencies. Prices and workloads change too often for a fixed break-even claim to remain reliable.
Use measured token volume, current invoices and an agreed depreciation period. Include the cost of the fallback path when the local model cannot meet the quality or latency threshold.
A bounded trial
Start with a low-risk task and no tool permissions. Compare LM Studio and Ollama using the same model file, prompts, evaluation set and hardware where possible. Add concurrency and network exposure only after the single-user workflow is understood.
The winner is the configuration your team can secure, reproduce and operate while meeting the task threshold. It may be either tool, or a cloud service, depending on the evidence.
Primary sources
- LM Studio developer documentation, reviewed 27 August 2026
- LM Studio server settings, reviewed 27 August 2026
- Ollama API introduction, reviewed 27 August 2026
- Ollama authentication documentation, reviewed 27 August 2026
- llama.cpp quantisation documentation, reviewed 27 August 2026
Turning this into a plan for your company?
Exceev connects your business goals to a practical technology roadmap, then puts AI to work in your products, workflows and existing systems.